Explainers: local AI
Q4_K_M vs Q5_K_M vs Q8_0: GGUF Quant Sizes Compared
Q4_K_M is 4.58 GiB, Q5_K_M 5.33 GiB on an 8B model: what the names mean and how much memory each needs.
Local LLM vs API: Data Boundaries and Operating Work
Compare local inference and hosted APIs by data flow, permissions, fallback and the work needed to run them.
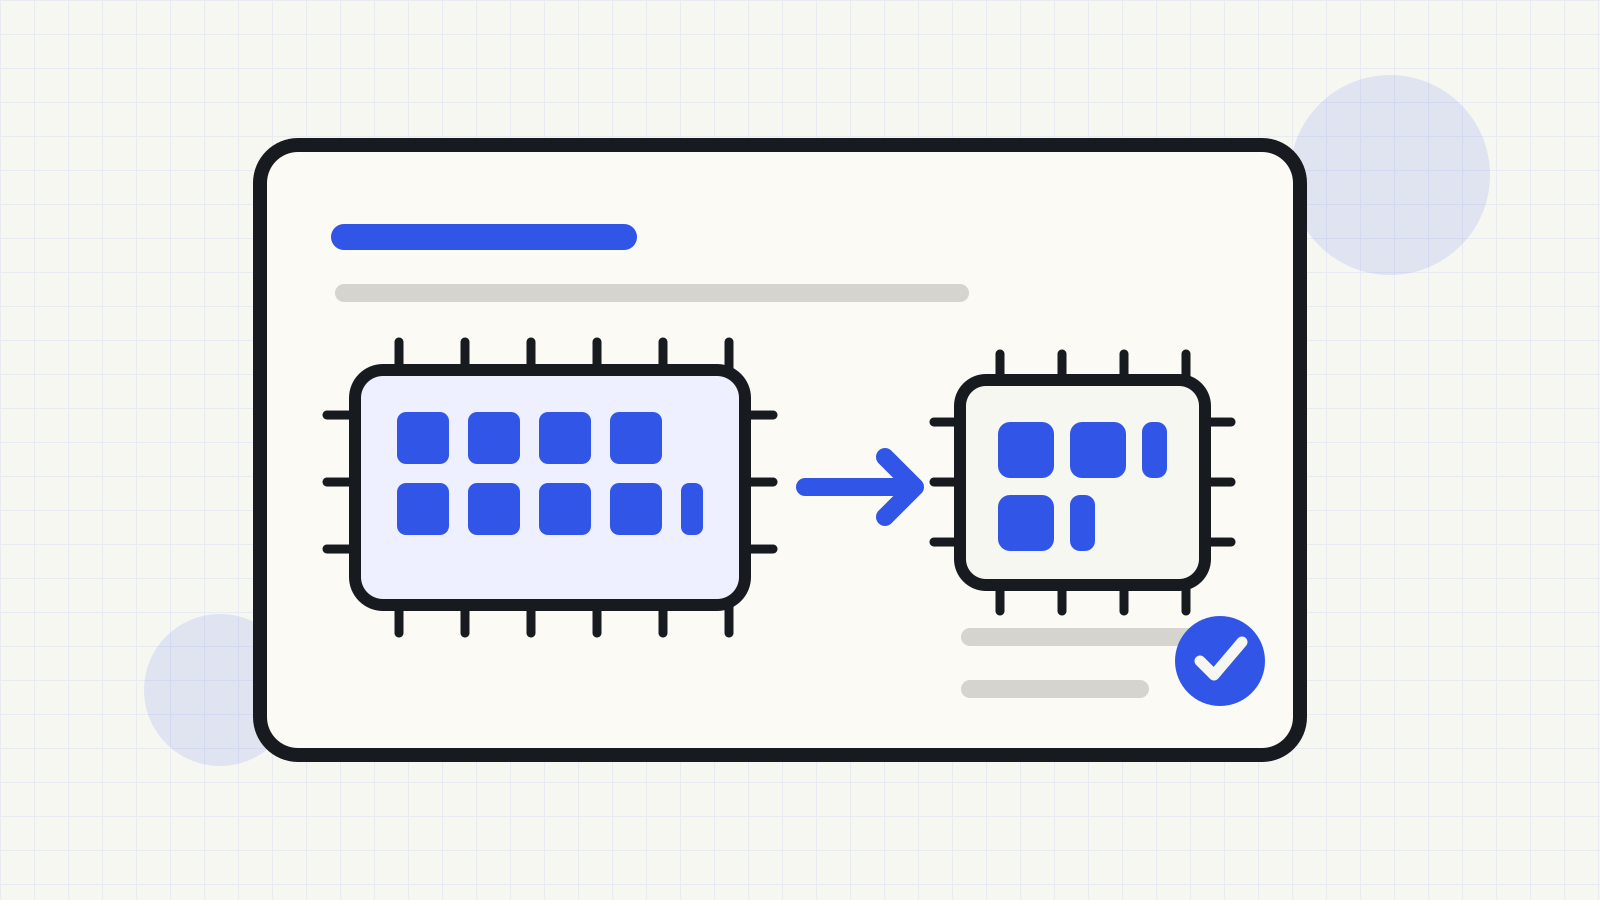
Model Precision Formats for Local AI
Model precision formats shape weight memory, compute compatibility and numerical behaviour in local AI.
KV Cache Memory: Why a Loaded Model Can Still Run Out
Model weights are only part of the memory budget. Longer sequences can add a substantial KV cache.
GGUF files explained: choosing a local model download
How to choose a GGUF download and check its encoding, companions, license and memory requirements.
Running AI Locally: What Your Laptop Can Handle
Memory, context length and model size determine whether local AI feels usable on your machine.